
1.
Pangram is the world’s best AI-text detection software. It has been so since 2024, where it compared favorably to GPTZero, Originality, and DetectGPT in all metrics (accuracy,1 false positive rate,2 and more.) Independent audits say the same. It achieved some notoriety in literary circles after Nabeel Qureshi claimed a regional winner of the prestigious Commonwealth Prize had generated their entire short story using AI and backed up his claim with another Twitter user’s Pangram screenshot. Most recently, it’s been integrated into Substack itself.
There’s a lot of Substack discourse about Pangram, AI detection, false positives, and more. Most of it is bad. I feel no particular desire to engage with people who say Pangram keeps marking their own human-generated text as AI; I’ve seen Pangram’s CEO Max Spero reply to tweets, Reddit comments, and more asking for proof, even offering a monetary bounty, and proof is never produced.3 I suspect they’re either themselves indeed using Claude or ChatGPT to generate text, and thus incentivized to downplay Pangram’s effectiveness, or they’re confused about what Pangram is, in that they believe each and every AI detector online is Pangram, much in the same way that every brand of tissues is Kleenex.
There is an exception to the bad discourse. Substack luminary Freddie DeBoer argues, in I Wouldn’t Say Pangram is Broken, But I Would Say That It’s Brittle, that Pangram is overconfident, and that it is easy to generate false positives—or at least, AI-assisted text that gets flagged as 100% AI-generated. He takes a paragraph he wrote and appends three ChatGPT-generated sentences to it, about one-third the length of his own words, and you can see the Pangram output for yourself: 100% indeed.
But that was Pangram 3. Pangram 4 succeeds where its predecessor fails, identifying exactly which sentences were AI-generated.4
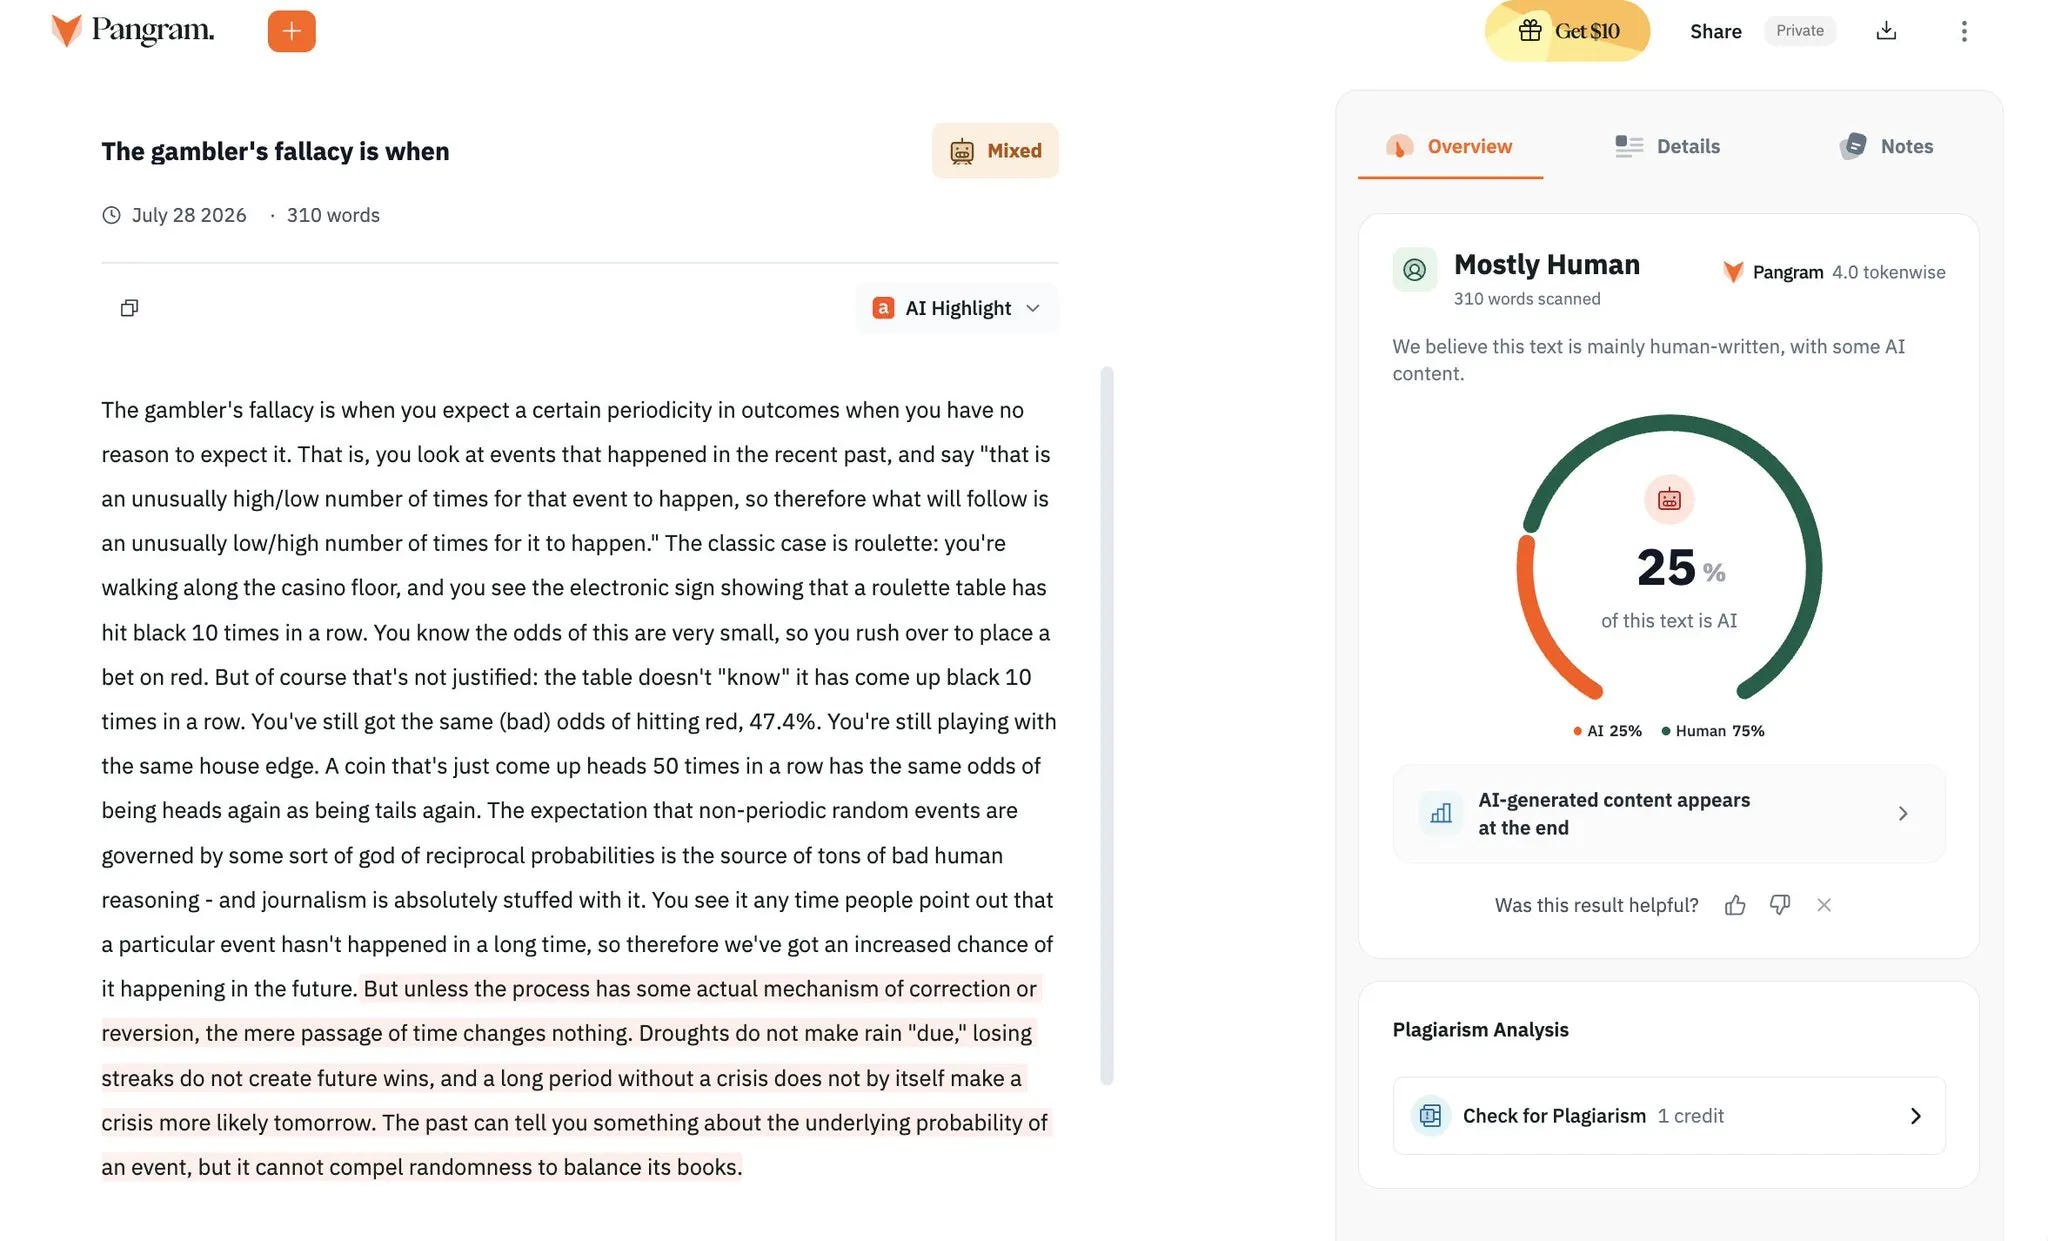
Pangram itself asserts a one in 24000 false positive rate against texts they’ve confirmed as human-written in their most recent technical report. I don’t endorse trusting companies blindly about their own products, but I haven’t seen any reason to believe those who blather about false positives then stay silent when prompted for evidence.
2.
What, then, should we do when someone claims a Pangram false positive?5
I’ll put aside, for now, the questions of academic integrity; leave that to the schools. I’m talking about how we should react when someone on Substack (or Twitter, or Wordpress, or a news site) claims a false positive.6
Earlier this summer, I read a Twitter post that felt strongly of AI. I didn’t care enough to think too hard about it, so I replied “@Pangram slop :)”; Pangram evaluated the text as 100% AI-generated. Here’s what the author said:

I thought about it for a bit, then replied to them with the tells that I’d subconsciously extracted from the writing: Claude-esque usage of the word “fold”; reliance on “quiet” and “that feel earned”; “is real”; “honestly”; a frictionlessness to it all. They said, “this is so sad i use honestly in pretty much all my posts.”
3.
At 9:17 of Jesser’s video Guess the Secret NBA Player ft. Luka Doncic, Jesser’s crew and Luka watch mystery contestant #3 shoot a sidestep three-pointer. Within seconds, someone says, “I recognize that jumper.”
Luka says, “Danny Green.”
Everyone in the NBA has a sidestep three. But Luka clued in on Green instantly. Beyond noting the shot type, he processed a thousand invisible details—posture, rhythm, release point, everything else one’s shooting form comprises—and assessed mystery contestant #3’s identity correctly.
Just like NBA players, AI models (ChatGPT, Gemini, Claude, and more) have their own statistical signatures, distinct flavors. Em-dashes, tricolons, and negative parallelism are analogous to posture, rhythm, and release point: they’re easy to describe and easy to see. But Luka and Pangram pick up on the less visible details, too, the details that take a few passes to synthesize and then verbalize. In fact, the models have a statistical signature strong enough to be visualized.
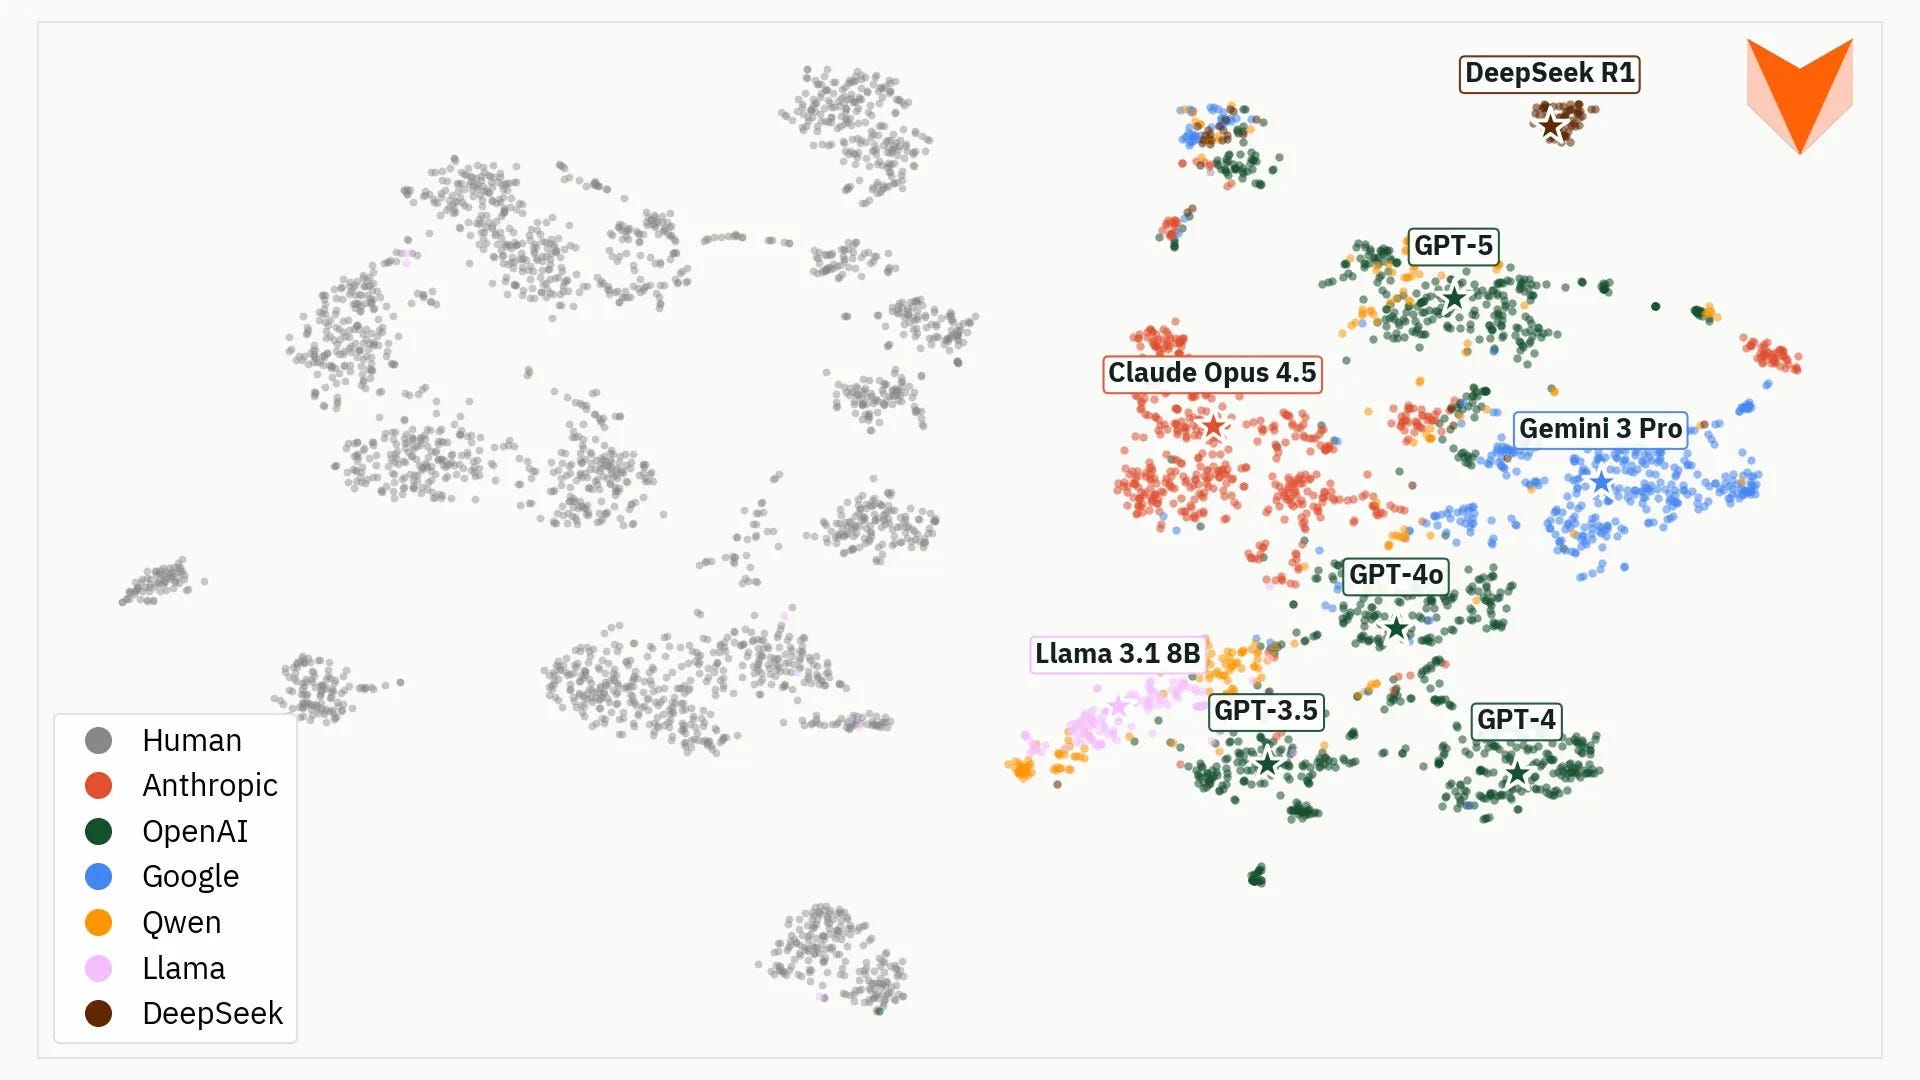
Then, when someone like our writer from Section 2 claims Pangram falsely marked their post as AI-generated, what that really means is that they write with the same statistical signature that the models do—that they, even beyond any instances of obvious “AI tells,” have written in a manner that carries the stench of AI.
Jon Repetti, in his piece Escaping a Hostage Situation, argues that theories of art that claim art to comprise a series of choices are correct—“in the most vulgar sense”—but incomplete.
In art, we don’t begin from choice, but from cliché, from a position of determination and dependency. And every actual choice we make in the production of an artwork is achieved by consciously cultivated tactics of resistance to cliché.
Suppose indeed that our aforementioned writer did not use AI. Then they have replicated this statistical signature, intentionally or not. If intentionally, then they have chosen to write in the decade’s dominant, clichéd style; they have chosen to emulate what the world believes to be and understands as generic slop. This choice seems almost unimaginable to me, so let us assume they did so unintentionally. Then they have absorbed AI’s invisible tics so thoughtlessly and thoroughly that they did not, for a moment, while writing or editing (if they even edited), consider how their text might be perceived. That in and of itself seems to indicate a dearth of the thought I believe to be necessary to generate great writing: no “consciously cultivated tactics of resistance to cliché,” none whatsoever. No consciousness, indeed.7
Bluntly, if my own style matched the AI house style, I would change my style.8 If two years down the line AI co-opts my voice, I will change my voice. I will change my voice any and every time this occurs. That is choosing against cliché. I haven’t removed em-dashes, tricolons, or negative parallelism from my writing—people who do, I think, are overly cautious; detector software will not flag text just for these surface features—but the moment Claude Odyssey 9 produces text that seems irrevocably me, I will adapt.9
After I replied to our aforementioned writer’s question with a chain of AI tells, they liked my tweets, then hid my reply. Another Twitter user posted another AI detection screenshot in response to their original post; I forget whether it was Pangram or not. They hid that, too, but eventually I think they saw the writing on the wall and deleted the post.
The writing was, though, cross-posted to a post on their blog, which they did not delete. Here’s the output from Pangram 4, the newest model: We believe that this entire text is AI. Me too, Pangram: AI-edited, thoroughly, with some human component, of course.
(I have very little respect for this reaction.)
4.
I must add some caveats.
Back to Freddie DeBoer. Pangram 4 marks this section of one of his posts as 100% AI-generated (paraphrased or rewritten, at least), whereas I believe it’s human-written and so does Pangram 3, at least when you feed it the entire post. So I think there are some false positives. DeBoer, though, has an excellent, decades-long track record. It’s one thing for him to explicitly link to Pangram claiming his work is AI-generated and defend it; it’s another thing, a coward’s stance, to hide replies tagging Pangram, delete your tweet, and keep your blog post up. One must still exercise their own judgment.
I believe the probability of replicating AI’s statistical signature to be low, almost vanishingly so. Almost. It’s possible to do so, especially in very short bursts of text, in which cases I don’t put that much faith in Pangram.10
5.
(As an endnote: I really do think their software is quite impressive. I had Claude Fable 5 on High generate 100 random numbers of its own choice twice; Pangram marked them both as AI-generated. I asked it to use software to generate 100 random numbers twice; Pangram marked them both as human-generated. Here’s the link to the Claude chat; now the Pangram links. This should be a strong indicator that the statistical signature argument I make is correct.)


The accuracy is the proportion of correct classifications. Suppose we have a dataset of 60 pictures of birds and 40 pictures that do not contain birds. Suppose a model says 53 of those bird pictures contain birds (and seven do not), and it says 38 of those pictures without birds do not contain birds (and two do.) The model’s accuracy is (53 + 38)/(60 + 40) = 91%.
Consider the same dataset as in the previous footnote. The false positive rate is the proportion of true negatives that get incorrectly classified as positives. There are 40 true negatives (pictures that do not contain birds) and two get incorrectly classified as positives. The model’s false positive rate is 2/40 = 5%.
It’s not hard to find his Reddit account; it’s quite funny, too.
There really still is some weirdness, though. More on that later!
Here I care only about Pangram false positives post-AI. I think Pangram false positives pre-AI are fine, in that I don’t feel negatively disposed toward them in the way I’ll later describe. They don’t apply to my argument.
I don’t care about extremely formulaic writing: cover letters, résumés, (some) grant applications, and similar. I also don’t care about human writing designed to trick Pangram, as DeBoer shows in a more recent Pangram-related post.
The natural implication being that I don’t care when people assert semantic drift, the corruption of people’s writing styles due to the influx of AI-generated text. Be stronger! Resist!
I have plenty of respect for Natasha, to be clear, but I don’t agree with this advice. If you write like the models, consider not doing that!
I’ve fed Fable my entire corpus of writing (I don’t particularly care if the models imbibe it) and it still can’t generate writing that sounds like me, but maybe Fable is worse than some of the other models at this. Maybe I’ll go for a ChatGPT Pro account soon to test out Sol.


You’re right to push back
I cannot help but share…I deal with a lot of college comp students trying to avoid doing the work for the grade, and what I saw for the first time last semester was WEIRD writing with super atypical inhuman errors—not clearly the bland AI bullshit I usually see with its telltale lack of writing errors. Baffled, I threw it into Pangram and it came back as 100% AI generated with a purple flag: humanized.
The errors the AI re-infused into the text to “humanize” it were so SO inhuman that my brain identified it as AI anyway.
I’ve been incredibly impressed with Pangram’s capabilities.